Your rack becomes an AI factory.
Start with three nodes and keep adding worker nodes. Every node you add brings the same tenants, models, metering and controls. You own all of it.
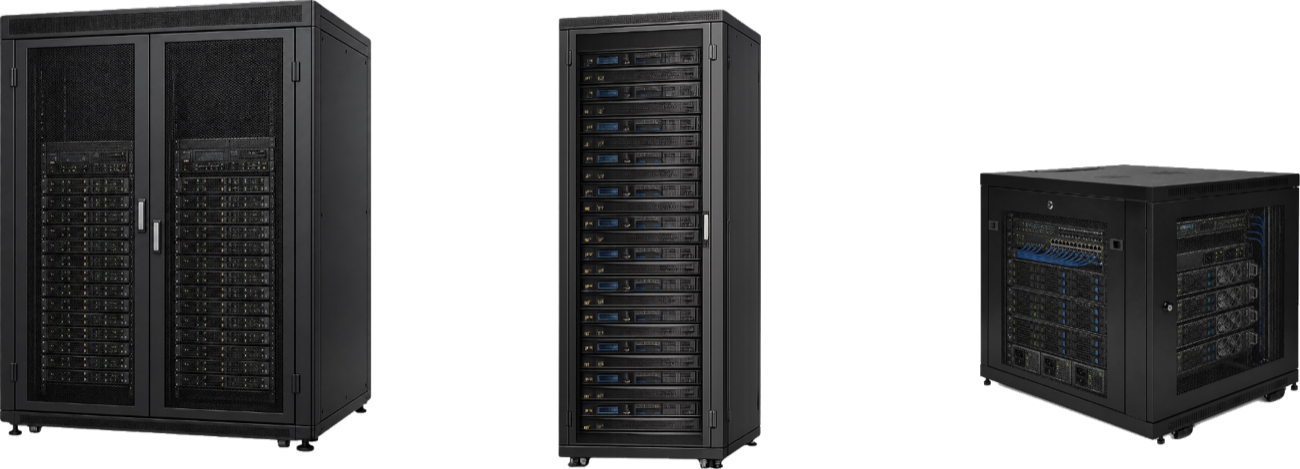 Your hardwareThree servers in your rack, then more500+ people at once
500+ people
At once, on three nodes.
Keep adding nodes
Same tenants, models, metering and controls.
100% on site
Prompts and documents stay home.
 500+ people at once
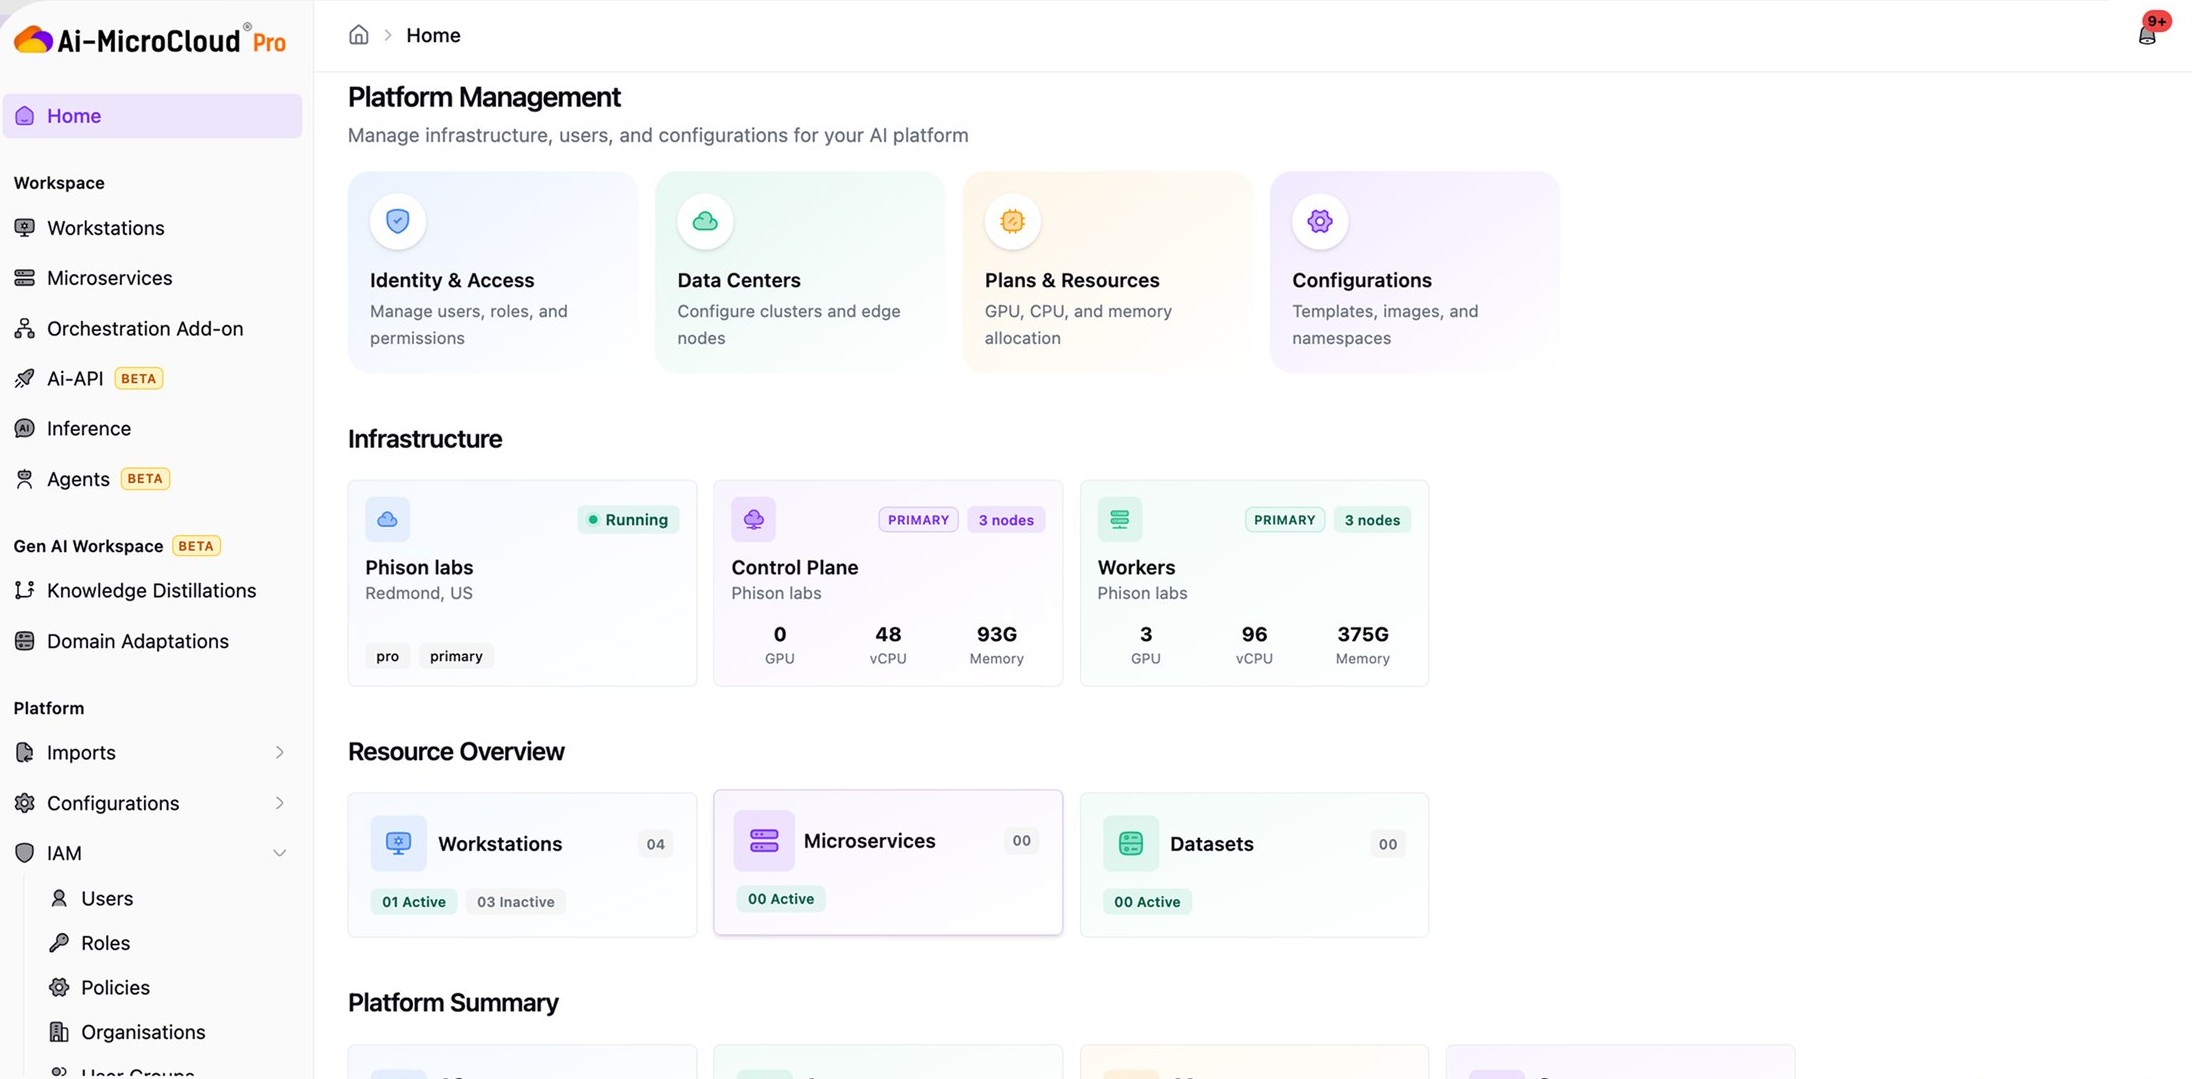
Data Center view
Runs on, for example
- A full rack
- Three NVIDIA DGX systems
- Three GPU servers
Your hardware, or ours through partners. Same software on all.
At enterprise scale
Every team. One private AI.
Hundreds of people work on the same models, in house, with their own quotas and keys.
Your rack. Real numbers.
people at once on three nodes¹
users, with context offloading¹
secure, in house, on three full nodes¹
of prompts and documents
What teams run on it.
Code generation
Without token limits. Your code stays in house.
Secure, scalable search
Across your confidential data, inside your perimeter.
One platform. Two ways to run it.
AI factory
Every team on shared GPUs, with quotas and plans. Add nodes as teams join.
Sell AI capacity
Isolated tenants, per-key metering, expiring keys and audit logs.
See it in action.
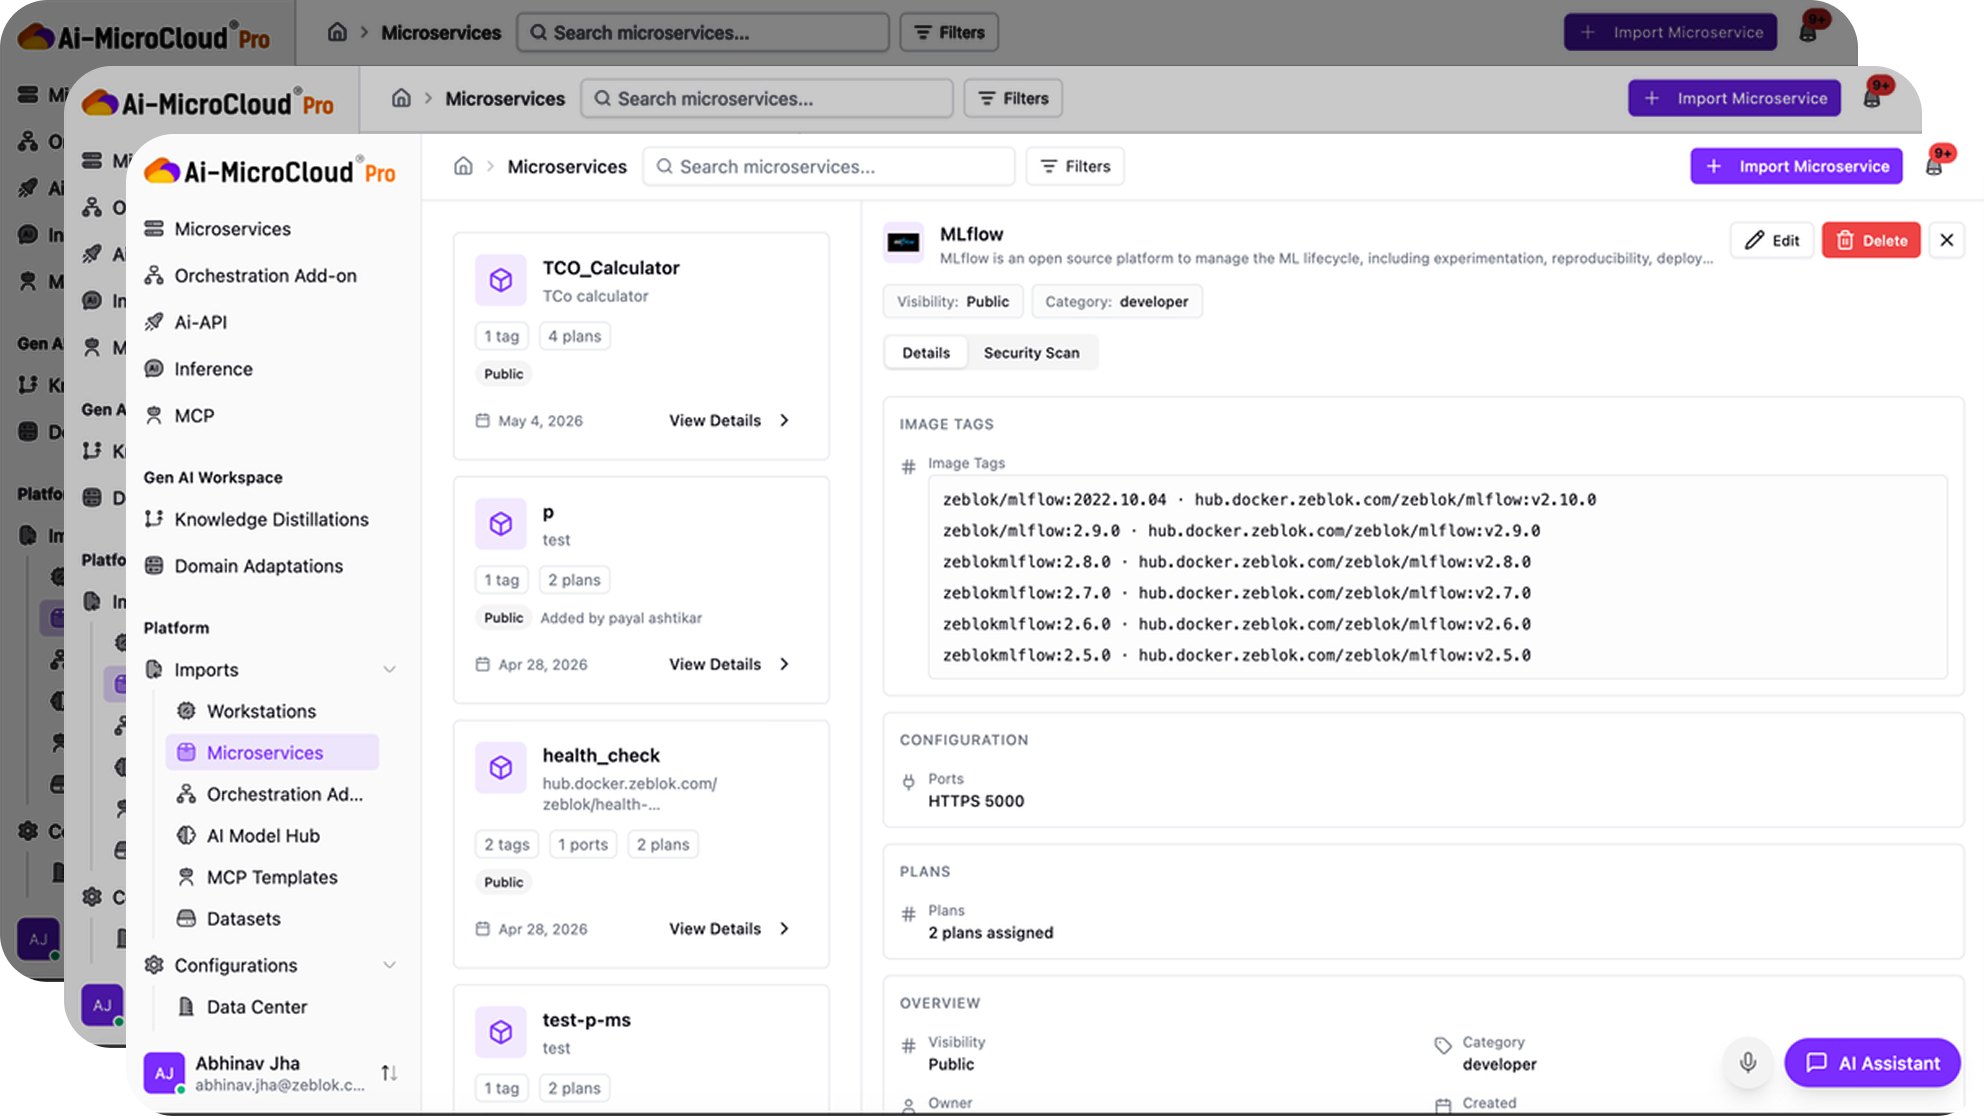
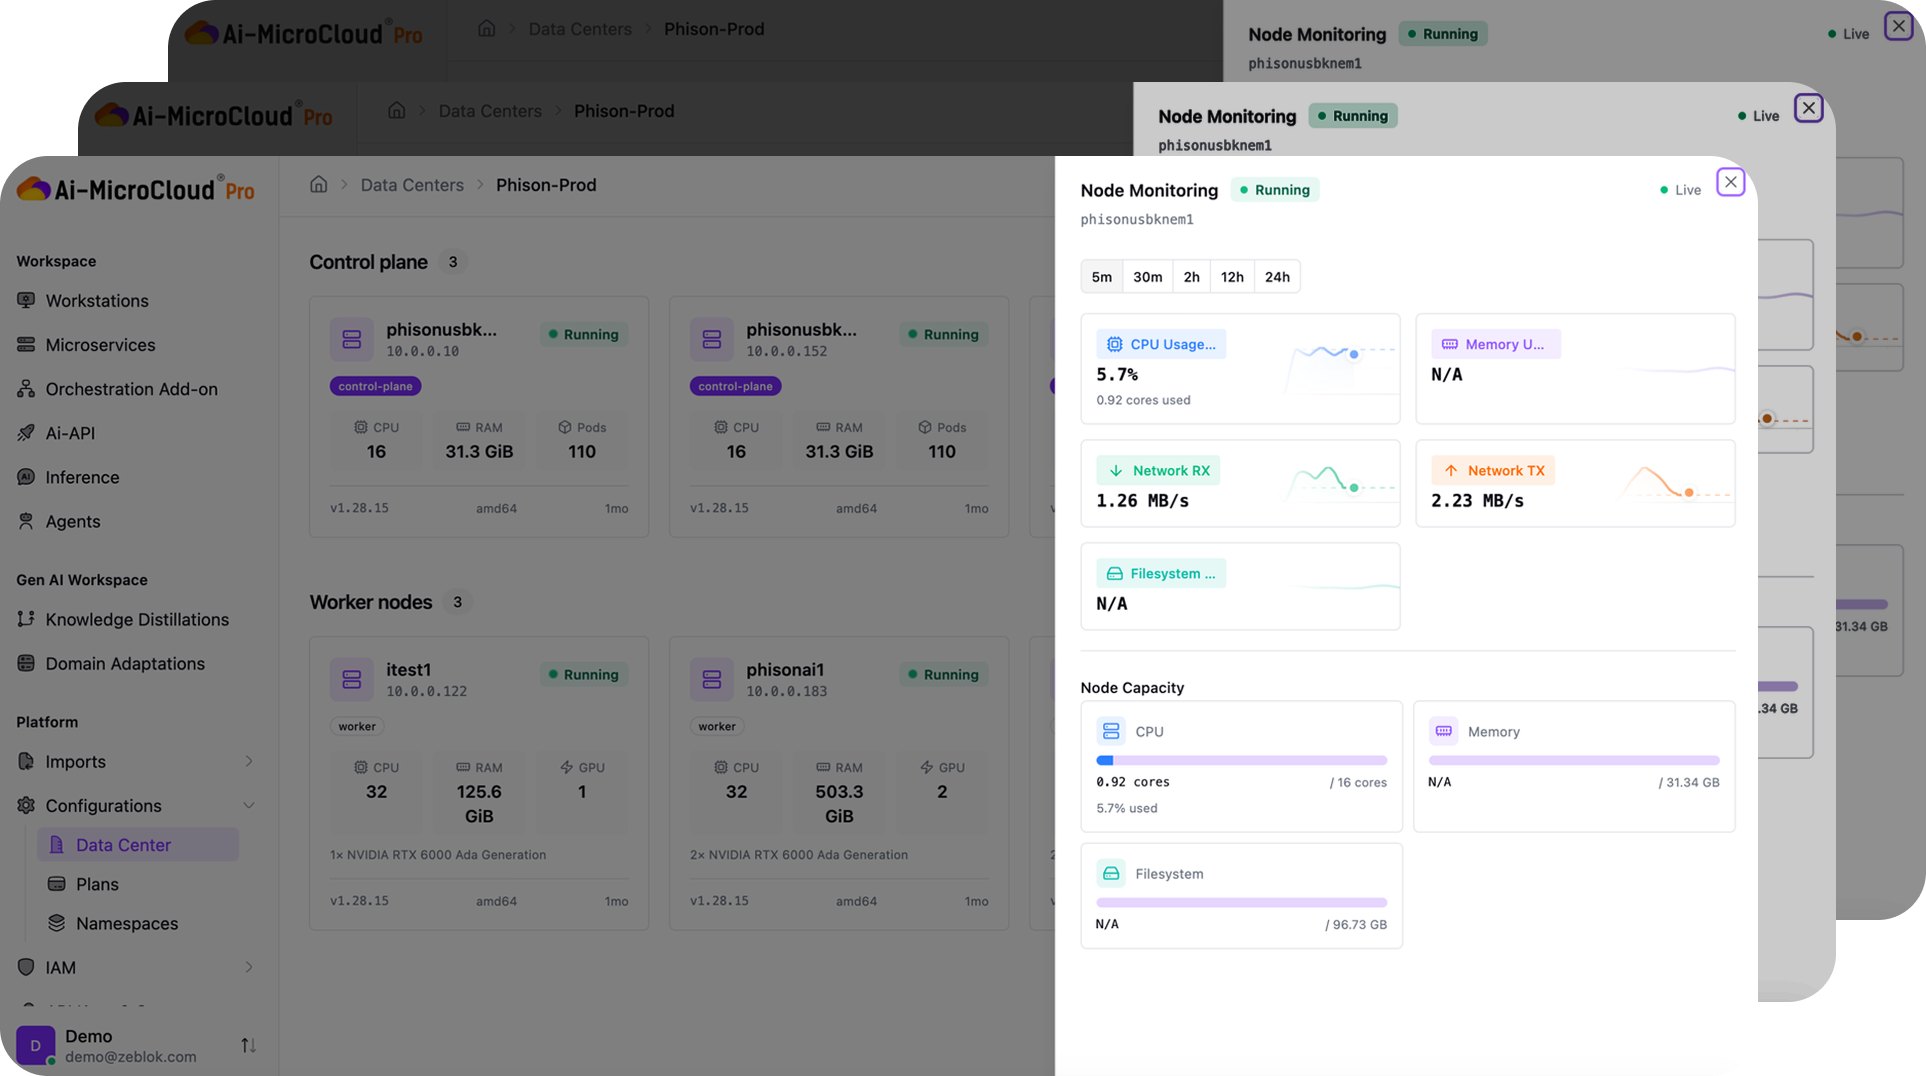
Start with three nodes. Keep adding.
Three-node starting configurations. Add worker nodes for more.
142 chats at once · 15.6M tokens an hour
228 chats at once · 27.8M tokens an hour
342 chats at once · 41.7M tokens an hour
534 chats at once · 73.5M tokens an hour
Same people. Half the GPUs.
four nodes down to two
with context offloading¹
estimated from component ratings¹
¹ Full details and test conditions in the datasheet.
See it running in
your environment.
Same Launcher. Your VPC, your data center, or your air-locked Private AI.